

You know how fast AI models outgrow the hardware they started on? AI Infrastructure is the set of hardware, software, networking, and data solutions that keeps training and deployment from stalling out.
If you plan it well, you stop treating GPUs as a black box and start treating your stack like a production system you can scale.
Below I break down the core components, what to watch for in power, cooling, networking, and storage, plus the operations and automation that make it manageable.
Podcast – Most Teams Learn AI Infrastructure the Hard Way. Here’s the Shortcut.
Interactive Power Cost Calculator
AI GPU Power Cost Calculator
Find out exactly how much your AI cluster costs to run — per day, month, and year — based on GPU type, count, and your electricity rate.
⚡ Select Your GPU
🖥 Cluster Configuration
Your AI Cluster Power Cost
This calculator provides estimates for planning and budgeting purposes only.
Actual costs depend on GPU power caps, server efficiency, cooling overhead, and utility rates.
GPU TDP values are based on publicly available manufacturer specifications.
For accurate infrastructure budgeting, consult with a data center specialist.
Data sourced from Uptime Institute 2024 regional PUE averages and NVIDIA published specifications.
© https://infofina.com — AI Infrastructure Resources
Key Takeaways
- AI infrastructure blends accelerators (GPUs like Nvidia H100 and B200, and TPUs), compute servers, networking, storage, and MLOps so you can train and serve large AI models reliably.
- Intra-node links (like NVLink inside multi-GPU servers) and inter-node fabrics (like InfiniBand NDR at 400 Gb/s or specialized Ethernet) help distributed training behave like a single coordinated system.
- Plan power and cooling as first-class constraints: H100-class accelerators can run in the hundreds of watts per GPU, and dense racks push many sites toward direct-to-chip liquid cooling.
- Storage choice is a performance decision, not a procurement detail: pair fast shared storage for checkpoints with scalable object storage for datasets to reduce restarts and wasted compute.
- Modern operations lean on Kubernetes, containers, and MLOps tools (Kubeflow, MLflow, and monitoring stacks) to automate deployment, scaling, model tracking, and drift detection.
- Use a simple acceptance bar before you scale: validate networking, storage throughput, scheduling behavior, and failure recovery on a small “scalable unit,” then replicate.

Core Components of AI Infrastructure
AI infrastructure combines powerful compute with fast data movement. If any one layer falls behind, your GPUs wait, your costs climb, and your iteration speed drops.
For most teams, the practical goal is simple: keep accelerators fed with data, keep multi-node training in sync, and keep deployments predictable as workloads change.
What are GPUs and TPUs used for in AI acceleration?
GPUs and TPUs turn data into model power.
GPUs and TPUs speed up neural networks by running the same math in parallel across many cores. For large training jobs and high-throughput inference, teams often standardize on platforms like the Nvidia H100 and B200 GPUs to get predictable performance and tooling across projects.
Power and heat are part of the accelerator decision. NVIDIA’s published specifications list H100 SXM configurations up to 700 W TDP, which is why planning for power delivery and cooling capacity has to start early.
Inside a multi-GPU server, high-bandwidth GPU-to-GPU links can be the difference between strong scaling and communication bottlenecks.
NVIDIA has described DGX H100 systems as providing 900 GB/s of NVLink connectivity between GPUs, which is exactly the kind of “scale up” bandwidth you want before you “scale out” across the network.
TPUs matter most when your software stack and workflow fit them. In its current Cloud TPU documentation, Google lists TPU v5p HBM bandwidth at 2,765 GB/s per chip, and TPU v5e pod designs.
With multi-terabit networking. Numbers that can change what “data hungry” looks like in practice if you run TensorFlow or JAX at scale.
- Pick GPUs when you need broad framework support, a mature ecosystem, and flexibility across many workloads.
- Consider TPUs when your training stack already aligns with TPU tooling and you want a purpose-built path for large-scale matrix math.
- Budget for the full system: accelerator power, networking, storage, and operational tooling usually decide success more than peak compute alone.
How do compute servers scale AI workloads?
Compute servers knit accelerators into clusters, then rely on the right topology to scale. A good design treats “scale up” and “scale out” as separate problems with separate bottlenecks.
On the networking side, many reference architectures split traffic into two paths. A front-end network for user access and storage access (north to south), and a cluster interconnect network for GPU-to-GPU traffic (east to west).
That separation keeps training communication from fighting with login, monitoring, and storage traffic.
Use a small, repeatable building block before you grow. NVIDIA and many infrastructure vendors publish “scalable unit” patterns (for example. A small set of nodes with a known switch layout) so you can replicate proven performance instead of redesigning every expansion.
| Scaling choice | What you’re optimizing | Common bottleneck | What to do about it |
|---|---|---|---|
| Scale up (more GPUs per node) | Faster intra-node training steps and large-batch efficiency | GPU-to-GPU communication inside the server | Prioritize NVLink and balanced PCIe layouts, and validate topology-aware collectives (NCCL for many GPU stacks). |
| Scale out (more nodes) | Bigger models, bigger datasets, shorter wall-clock time | Network fabric congestion and synchronization overhead | Use low-latency fabrics (InfiniBand or tuned Ethernet), avoid oversubscription, and isolate cluster traffic. |
| Hybrid (scale up then scale out) | Practical growth path for most teams | Cross-layer tuning effort | Standardize a “golden” node image, automate provisioning, and use a clear acceptance bar for performance and recovery. |

Teams plan how much power a server will use. One example used an 8-GPU server running at full power. It drew 3.6 kW of compute power total.
The building’s systems bumped that up to 4.5 kW. Electricity cost about 0.12 dollars per kilowatt-hour used. That added up to around 12.96 dollars per day.
Monthly, the cost came to about 388.80 dollars. Adding 10% for maintenance raised it to 427.70 dollars. Planners use this method to compare costs before buying. Your real costs depend on your actual hardware and settings.
Interactive AI Stack Component Visualizer
AI Stack Component Visualizer
Every AI system is built in layers. Tap a layer below to see what lives there, which tools run it, and why it matters.
Orchestration & MLOps
Deployment, scaling & monitoring
▾
Networking
Moves data between GPUs & nodes
▾
Storage
Datasets, checkpoints & recovery
▾
Compute (Accelerators)
The foundation — GPUs, TPUs & servers
▾
This visualizer is an educational simplification of AI infrastructure architecture. Real-world stacks vary by scale, vendor, and workload.
Specifications referenced (GPU TDP, NVLink/InfiniBand bandwidth) are based on publicly available manufacturer documentation.
© https://infofina.com — AI Infrastructure Resources
Why are power and cooling systems critical for AI hardware?
AI GPUs and TPUs generate intense heat during long training runs. If you cannot remove that heat, you will see thermal throttling (slower training), noisy failures, and shorter hardware life.
Power planning matters just as much as cooling. Dense AI racks can push electrical limits fast, and your facility constraints can become your real scaling limit even if you have budget for more GPUs.
For a baseline reference point, Uptime Institute’s 2024 regional reporting lists an average annual PUE of 1.46 for North America. That number helps you translate IT power into facility power, which is what your finance and facilities teams will care about.
- Start with a rack power target, then work backward into PDUs, circuits, and redundancy.
- Decide on air vs liquid early. If your GPUs run near their top power limits, direct-to-chip liquid cooling often becomes the simplest path to stable sustained performance.
- Design for continuous operation: think about maintenance windows, failover, and what happens during a single pump, fan, or PSU failure.
- Use power caps intentionally: a small power cap can reduce spikes and improve predictability, which can help you fit more usable compute into the same facility envelope.
Liquid cooling helps most during long, non-stop training runs. A lab team tested a 4-node GPU rack for 72 hours. They compared air cooling against a liquid cooling retrofit.
With air cooling, GPUs slowed down 18 times total. Clock speeds dropped by about 12 percent on average. After adding liquid cooling, slowdowns dropped to just once. Clock speeds only fell by 2 percent this time.
The lab lead said liquid cooling made throttling nearly disappear. Steady clock speeds make training time estimates more accurate. Stable systems are also much easier to plan around.
Networking and Storage
Networking and storage decide whether your compute stays busy. In distributed training, your cluster spends a surprising amount of time communicating gradients, parameters, and checkpoints.
So the goal is not “fast networking” in the abstract. You want the right bandwidth and latency in the right places, with predictable behavior under load.
What are high-speed interconnects and why are they important?
Interconnects move data quickly between nodes in a cluster. They control how fast training jobs sync up. They also help inference services spread requests across replicas.
InfiniBand NDR is popular in AI clusters for good reason. It reaches 400 Gb/s per port with low latency. It handles heavy traffic moving between nodes very well. Ethernet can also work, especially at 400 or 800 GbE.
But Ethernet needs careful tuning to avoid hidden bottlenecks. Many teams size their front-end network based on GPUs.
One guideline suggests 12.5 Gb/s per GPU for storage. It also recommends 25 Gb/s per GPU for user traffic. This helps you check if your design will bottleneck later.
Low latency and high bandwidth make clusters act like a single computer.
| Interconnect | Best for | What to watch |
|---|---|---|
| InfiniBand (NDR class) | Large-scale distributed training and tightly synchronized workloads | Fabric design, switch tiers, and ensuring your storage and management traffic do not leak into the training fabric |
| Specialized Ethernet (high-speed, low-latency designs) | Organizations standardizing on Ethernet operations and tooling | Congestion control, consistent latency under load, and avoiding oversubscription |
| Intra-node links (NVLink and similar) | Multi-GPU scale up inside a single server | Topology awareness in your communication library and correct GPU placement |
- Separate traffic classes: isolate training traffic from storage, management, and user access where you can.
- Validate with a real workload: benchmark all-reduce and checkpoint behavior, not just raw link speed.
- Watch your topology: the “best” NIC or switch does not help if GPU placement and routing force inefficient paths.
How do scalable data storage solutions support AI?
Good storage keeps large datasets ready and checkpoints safe. If storage slows down, your GPUs sit idle and wait. Slow checkpoints turn small failures into hours of lost work.
Pick the right storage type for each job you run. Object storage works best for datasets and long-term archives. Parallel file systems handle fast, shared access really well.
They shine during checkpointing and shared training data loads. Cloud file systems help you plan how much throughput you need. One example offers tiers of 12 or 40 MB/s per TiB.
This helps you estimate how much storage to provision. For GPU pipelines, reducing CPU overhead in the data path helps. GPUDirect Storage lets GPUs transfer data without extra CPU copies. This frees up your CPU for data prep and orchestration.
| Storage need | Good fit | Why it works |
|---|---|---|
| Durable datasets and long-term retention | Object storage | Scales cheaply, supports large volumes, and fits data lake patterns for big data and analytics |
| Fast shared checkpoints and shared training access | Parallel or distributed file systems (Lustre, BeeGFS, and similar) | High-throughput POSIX-style access helps multi-node jobs recover faster |
| Low-latency, small working sets | Local NVMe plus a shared checkpoint target | Local scratch is fast, shared checkpoints protect you from node loss |
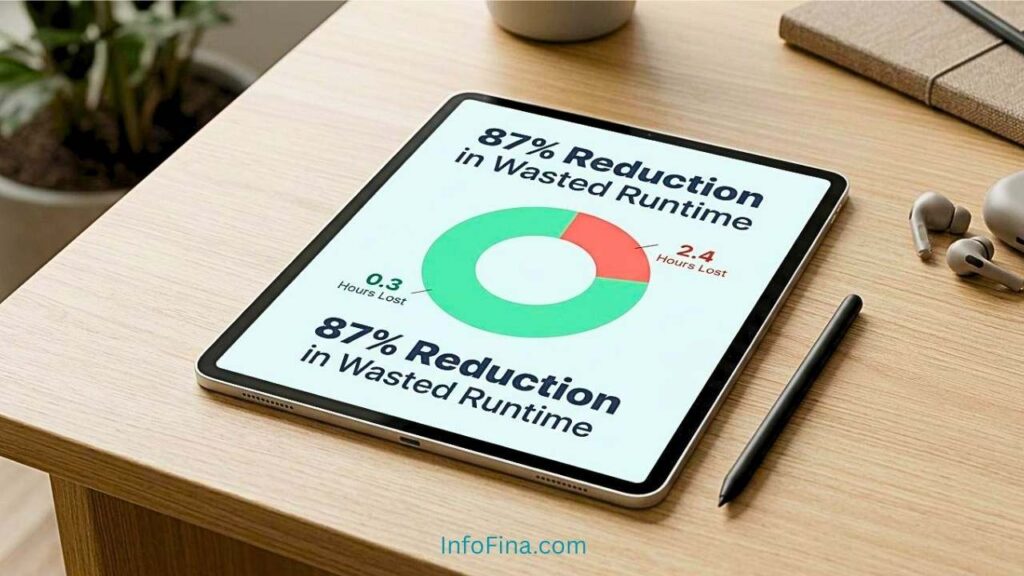
A test team tried to reduce wasted time during training runs. They used a 10-node setup and rewrote their checkpoint system. The old way saved snapshots locally on each individual node.
Failed restarts caused about 2.4 hours of lost compute daily. The new way saved coordinated checkpoints to shared object storage. Lost compute dropped to just 0.3 hours per day after.
That is an 87 percent reduction in wasted runtime total. The engineer said recovery time dropped dramatically after the change. Long training runs stopped wasting so much compute time overall. Good checkpoint design keeps your cluster running more efficiently.
- Checkpoint on purpose: set a checkpoint schedule that matches your failure tolerance, not a default you copied from a tutorial.
- Separate hot and cold data: keep hot training shards and checkpoints on high-throughput storage, keep archives on cheaper tiers.
- Test recovery: practice a node kill and a restart. If it is slow or flaky, fix it before you scale.
Software and Operations
Software and operations make the infrastructure usable. Without orchestration, repeatable environments, and monitoring, your “cluster” becomes a collection of one-off fixes.
The best setups treat Machine Learning deployment like any other production service: automated builds, controlled rollouts, clear observability, and fast rollback.
Which machine learning frameworks and orchestration tools are commonly used?
Here is a practical set of frameworks and tools teams use for AI workloads in production, along with what each one is best at.
| Category | Tool / Framework | What it does | Why teams use it |
|---|---|---|---|
| Framework | TensorFlow | Builds and trains deep learning models. | Offers production features and broad ecosystem. Good for large models and TPU support. |
| Framework | PyTorch | Provides dynamic graphs for research and production. | Preferred for fast iteration. Strong community and tooling. |
| Framework | JAX | Delivers high-performance numerical computing. | Simple API for advanced optimizations and accelerators. |
| Framework | scikit-learn | Handles classic ML models and preprocessing. | Lightweight, easy to use for modeling and baselines. |
| Framework | Hugging Face | Hosts pretrained NLP and multimodal models. | Saves time with ready models and pipelines. |
| Distributed compute | Ray | Scales Python and AI workloads across a cluster. | Useful when you want a unified way to parallelize data processing, training jobs, and serving logic. |
| Orchestration | Kubernetes | Manages containerized workloads at scale. | Standardizes deployment, scheduling, and isolation for shared AI environments. |
| Orchestration | Kubeflow | Runs ML pipelines on Kubernetes. | Brings training and pipeline structure closer to the cluster, which helps standardize repeatable workflows. |
| Orchestration | Docker | Packages models and apps into containers. | Makes builds reproducible and portable. |
| Orchestration | Argo Workflows | Executes CI/CD and batch pipelines. | Fits data processing, training runs, and scheduled retraining in Kubernetes environments. |
| Scheduler (common in HPC) | Slurm | Schedules batch jobs on CPU and GPU clusters. | A strong fit for training queues, fair-share scheduling, and multi-tenant research environments. |
| GPU operations | NVIDIA GPU Operator | Automates GPU software provisioning in Kubernetes. | Reduces drift by managing drivers, runtimes, and the Kubernetes device plugin as part of the cluster lifecycle. |
| MLOps | MLflow | Tracks experiments and manages model artifacts. | Helps with reproducibility and model registry tasks. |
| MLOps | Airflow | Schedules and orchestrates data and training jobs. | Fits ETL, feature pipelines, and retraining workflows. |
| Model serving | KServe | Serves models on Kubernetes with production-oriented primitives. | A practical option when you want standardized rollouts, autoscaling hooks, and cluster-native serving patterns. |
| Inference serving | NVIDIA Triton Inference Server | Runs optimized inference with features like dynamic batching. | Helps increase throughput by batching requests without forcing clients to batch. |
| Monitoring | Prometheus and Grafana | Collects time-series metrics and visualizes dashboards. | A common combination for cluster health, GPU utilization, and alerting on service regressions. |
| Infrastructure as code | Terraform | Defines and provisions cloud and on-prem resources from code. | Helps you version infrastructure changes and reduce manual configuration errors. |

How do MLOps tools help with AI deployment and monitoring?
MLOps tools turn ad hoc model work into a repeatable process. They help you track what you trained, what you deployed, and whether it still performs the way you expect.
For example, MLflow’s documentation describes its Model Registry as a centralized place to manage the lifecycle of models.
That is valuable in real deployment work because it gives you a clean path to promote a model to staging, then production, and roll back if a release degrades.
Pipeline tooling helps you keep training and deployment consistent. Kubeflow Pipelines runs workflows by launching Kubernetes pods for each step, which makes it easier to standardize data processing, training, evaluation, and packaging.
On the inference side, serving systems can raise throughput without changing your application logic. Triton documents “dynamic batching” as a server feature that combines requests into batches automatically. Which is a practical lever when you need better GPU utilization under spiky traffic.
- Automate deployments: treat model rollout like application rollout, with canary releases and fast rollback.
- Make drift visible: monitor input distributions, output quality proxies, and latency so you catch silent regressions.
- Version what matters: lock model weights, code, key configs, and training data snapshots to support audits and repeatability.
- Close the loop: feed production signals into retraining triggers, but require human review for high-impact changes.
Conclusion
AI Infrastructure ties hardware, software, networking, and data solutions into one working system so your AI models can train and serve reliably.
When you size power and cooling correctly, build low-latency networking, and choose storage that supports fast checkpoints, you protect performance and scalability.
Then software, automation, and MLOps turn that foundation into repeatable deployment and management, which is what keeps real workloads stable as demand grows.
FAQs
1. What is AI infrastructure?
AI infrastructure is the hardware and software that run AI, and support large language models. It includes processors, storage, network links, and data center services.
2. Why does AI infrastructure matter?
It lets software developers train models, analyze data, create content, and automate content creation.
3. What are the main components of AI infrastructure?
Processors power training and inference, storage holds data, and a fast network moves information. Software tools manage models and pipelines, and monitoring keeps systems up to date. Large language models need all parts to work well together.
4. How do teams build reliable AI infrastructure?
Start with a clear need, add processors and storage as you grow, and test performance often. Plan for implementing generative AI, support marketing automation, and keep human checks for quality.